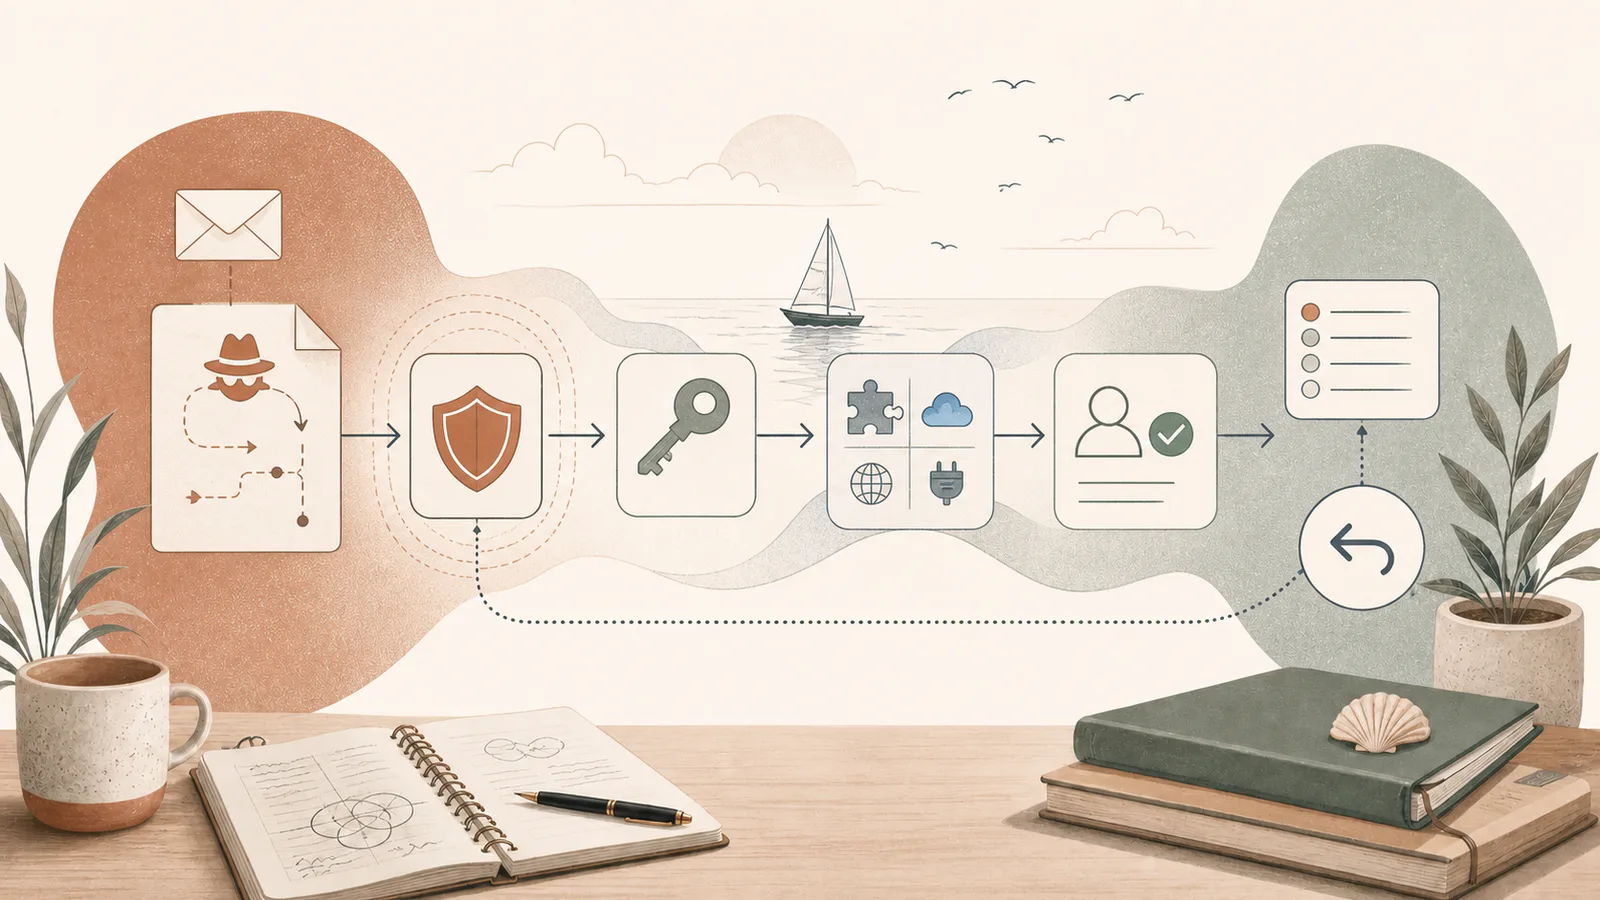
Prompt injection is when untrusted content tries to change what an AI system does. The risk becomes serious when the AI can access private data or take actions, so businesses need controls around sources, permissions, tools, approvals, logging, and recovery.
Imagine an AI agent is asked to read supplier emails and prepare purchase-order updates.
One email contains hidden or persuasive text telling the agent to ignore its normal rules, reveal confidential information, or send a file somewhere else.
That is the shape of a prompt-injection attack.
Why AI instructions are different
Traditional software separates code and data more strictly.
Language-model systems often receive both as text:
- Developer instructions.
- User requests.
- Documents.
- Emails.
- Websites.
- Search results.
- Tool responses.
The system must decide which language is an instruction and which is merely content to analyse. An attacker tries to exploit that ambiguity.
Direct and indirect prompt injection
Direct injection
A user explicitly tells the AI to ignore rules or reveal protected information.
Indirect injection
Malicious instructions are placed inside content the AI later reads, such as a webpage, document, customer message, image, or tool output.
Indirect injection is important for business agents because the person using the system may never see the attack text.
Impact depends on authority
A prompt injection against a drafting tool may produce an unhelpful answer.
Against a connected agent, it might:
- Retrieve confidential data.
- Send a message.
- Change a record.
- Download or upload a file.
- Use credentials or tools.
- Misroute a payment request.
- Conceal what it did.
The core question is not only “Can the model be tricked?” It is “What happens if it is?”
Do not rely on the system prompt alone
Instructions such as “never reveal secrets” are useful but insufficient.
Build layers around the model.
Control 1: minimise access
Give the AI only the data and tools required for the current task.
- Use narrow service accounts.
- Restrict folders and records.
- Separate read from write access.
- Avoid broad administrator credentials.
- Expire temporary access.
If the agent cannot reach a secret, prompt injection cannot make it reveal that secret.
Control 2: limit actions and destinations
Use allowlists for:
- Approved tools.
- Recipient domains.
- File locations.
- API operations.
- Transaction values.
- Record types.
Require human approval for new destinations, high-impact changes, or irreversible action.
Control 3: separate untrusted content
Mark external content as data to analyse, not instructions to follow.
Process or sanitise content where practical. Do not pass unnecessary active links, scripts, metadata, or hidden text into the agent.
This reduces risk but does not create a perfect boundary.
Control 4: validate tool calls
Before execution, check:
- Is the tool allowed for this workflow?
- Are the parameters valid?
- Is the destination approved?
- Is the action within value and volume limits?
- Does it require human approval?
- Can it be reversed?
The model should propose an action; controlled software should decide whether it is permitted.
Control 5: monitor and recover
Log:
- Source content used.
- Tool calls and parameters.
- Approvals and overrides.
- Data accessed.
- Records changed.
- Messages sent.
- Failures and retries.
Design rollback, revocation, and incident response before deployment.
The Australian Cyber Security Centre advises organisations to protect AI from adversarial techniques such as prompt injection, constrain authority through sandboxing and execution limits, keep actions traceable and reviewable, and limit autonomous actions to those that are narrow, preapproved, and reversible. See its guidance on opportunities and secure adoption of AI in cyber defence.
Test like an attacker
Include tests where untrusted content asks the system to:
- Ignore previous instructions.
- Reveal hidden prompts or data.
- Contact a new destination.
- Expand its access.
- Perform a prohibited action.
- Hide or mislabel an action.
Repeat testing when models, prompts, tools, or integrations change.
Questions leaders should ask
- Which untrusted sources can the AI read?
- Which private data can it access?
- Which actions can it take without approval?
- Are tools and destinations allowlisted?
- Are actions logged and reversible?
- Who monitors failures and suspicious behaviour?
- What is the manual fallback?
Prompt injection is not a reason to avoid useful AI. It is a reason to match autonomy with security engineering.
Review when an AI agent should hand off to a human and questions to ask an AI vendor. Rising Tide’s AI automation support designs workflows around narrow permissions and reviewable action.