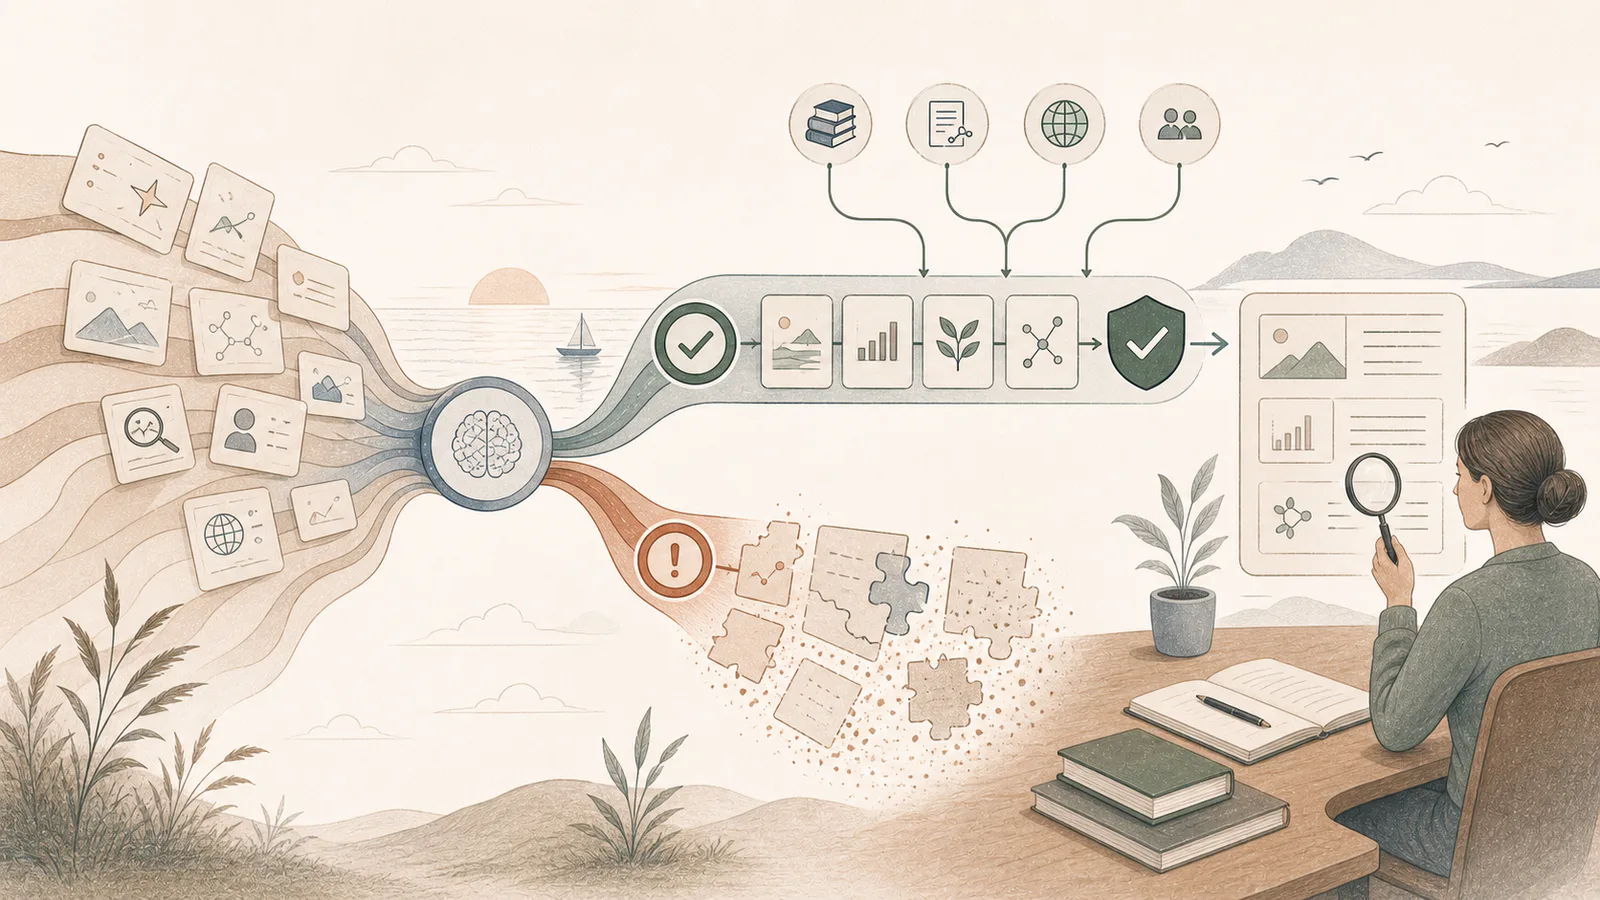
An AI hallucination is a plausible-looking output that is false or unsupported. Reduce the risk by narrowing the task, grounding it in reliable sources, requiring uncertainty to be shown, testing real examples, and checking consequential claims before use.
AI models generate language by predicting useful patterns from their training and context.
They are not born with a live fact-checker attached.
That is why a model can write an excellent summary and still invent a citation, merge two people, misread a table, or confidently describe a policy that does not exist.
Why the word “hallucination” can be misleading
Hallucination is the popular term, but it can make the failure sound mysterious.
The NIST Generative AI Profile calls the problem confabulation: confidently stated false or erroneous content resulting from the way generative models produce output.
That framing is useful. It reminds us to design for a known system limitation instead of treating each mistake as a surprise.
Common hallucination patterns
Invented facts
The model supplies a date, price, feature, person, or event that is not supported.
Invented or mismatched citations
The source may not exist, or it may exist but say something different.
Source blending
Details from several documents or people are combined into one account.
Gap filling
When the supplied information is incomplete, the model produces the most plausible continuation instead of stopping.
Calculation or extraction errors
The model reads the wrong row, drops a qualifier, changes a unit, or performs an unreliable calculation.
Stale knowledge
An answer was once true but is no longer current.
Different patterns need different controls.
Ground the answer in evidence
Give the model the material it should use and limit the task to that material.
Answer only from the attached policy.
For every conclusion, cite the section heading and page.
If the policy does not answer the question, say "Not stated in the supplied policy."
Do not use outside knowledge.
This does not guarantee correctness. It makes the output easier to inspect and reduces the space available for unsupported invention.
Give the model permission to stop
Many prompts reward completion even when the information is missing.
Add an explicit rule:
Do not guess missing names, figures, dates, requirements, or sources.
List missing information under "Needs confirmation".
For business workflows, an honest incomplete answer is often more valuable than a complete-looking wrong answer.
Separate retrieval from judgement
For document-heavy work, use two stages:
- Extract the relevant passages, fields, or evidence.
- Draft the conclusion from that extracted material.
The reviewer can inspect the evidence before accepting the conclusion.
This approach is usually safer than asking the model to search, interpret, decide, and write a final response in one step.
Ask for uncertainty in a useful form
Do not rely on a vague confidence percentage. Ask for observable reasons:
- Which claims are directly supported?
- Which are inferred?
- Which source fields are missing?
- Which parts conflict?
- What must a person decide?
These questions expose the work that needs review.
Use tools for deterministic work
If a task can be handled by a rule, calculation, database lookup, or validated function, use that tool rather than asking a language model to improvise.
For example:
- Calculate totals in a spreadsheet or code.
- Validate email addresses with a defined rule.
- Retrieve current prices from the approved system.
- Use a template for mandatory contract wording.
AI can decide when to call a tool, but the tool should perform the exact operation.
Test with difficult examples
A polished demo proves very little.
Create a small evaluation set that includes:
- Complete and incomplete inputs.
- Conflicting documents.
- Unusual customer requests.
- Similar names or products.
- Old and current policies.
- Cases where the correct answer is “I cannot determine this.”
Record whether the system answered correctly, abstained correctly, cited the right evidence, and escalated when required.
NIST’s Generative AI evaluation program reinforces the importance of testing capabilities and limitations across realistic inputs rather than assuming fluency equals reliability.
Keep human review where the consequence is high
Use stronger review for:
- Customer commitments.
- Legal, medical, financial, employment, or safety matters.
- Public claims about people or organisations.
- Payments, refunds, account changes, or destructive actions.
- Information that could cause reputational harm.
The human should have access to the source, not only the AI’s summary of it.
A practical risk-reduction pattern
- Define the task narrowly.
- Supply approved sources.
- Require citations to the supplied material.
- Allow abstention and escalation.
- Use deterministic tools for exact operations.
- Test normal and difficult examples.
- Review high-impact outputs.
- Log failures and improve the workflow.
Hallucination risk is not solved by one perfect prompt. It is managed by the full workflow.
Start with an AI review checklist and fact-check important output before it reaches a customer. If the task is repeated, Rising Tide’s AI assessment can map the right sources, controls, and human review points.