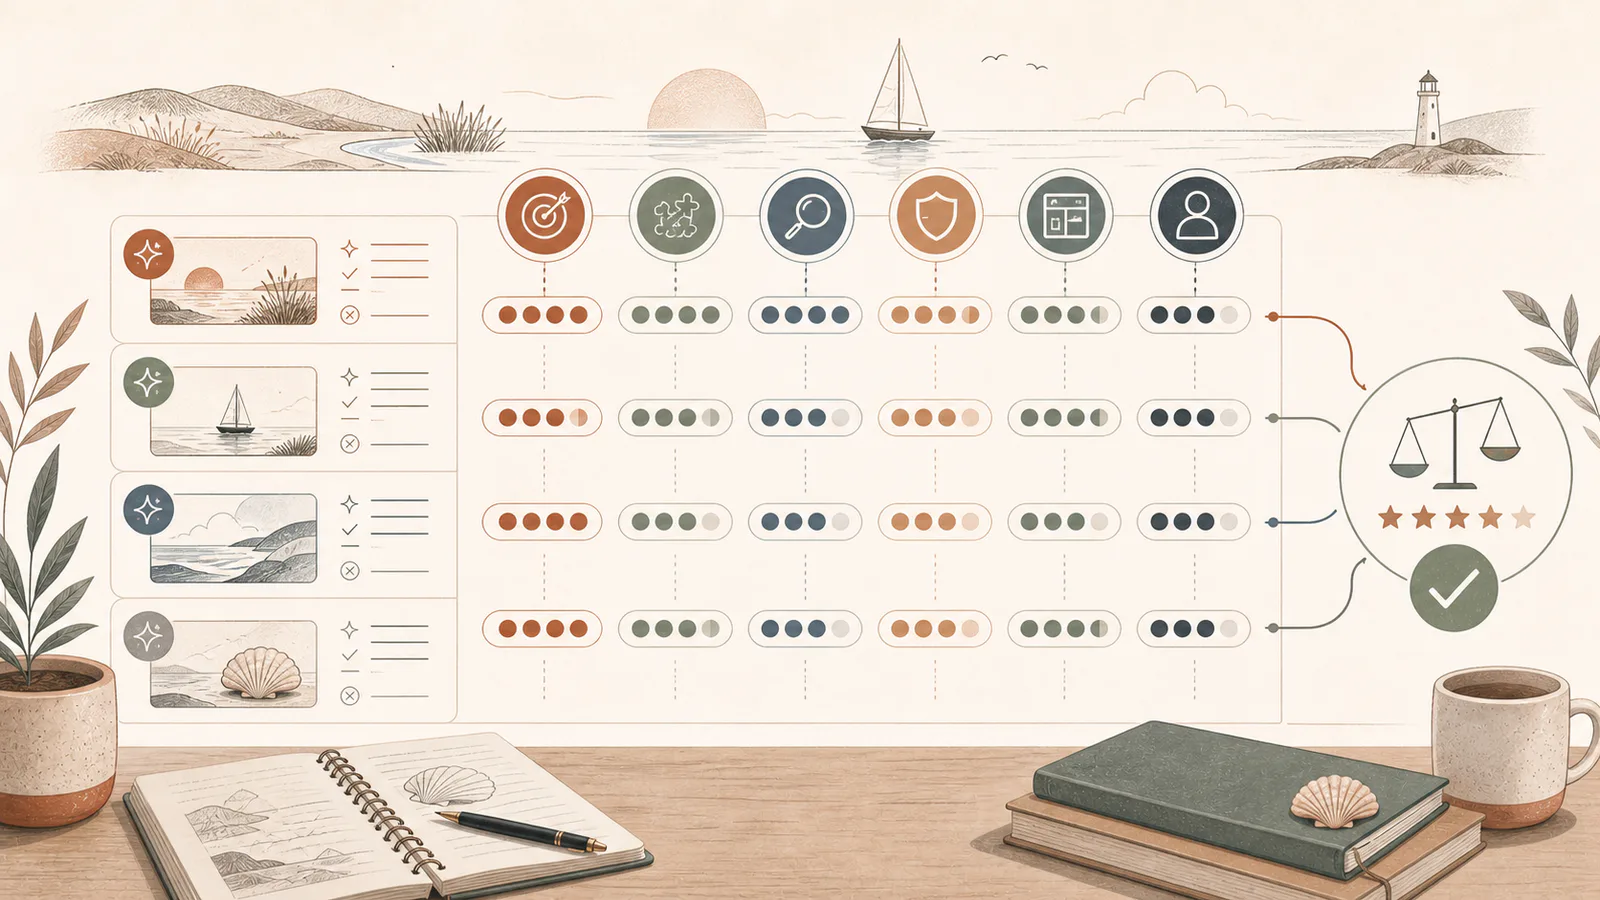
Evaluate AI output with a rubric that reflects the real task. Score correctness, completeness, evidence, boundaries, usability, and review effort, then define any critical errors that automatically fail the result.
AI quality is difficult to improve when feedback is limited to “good,” “bad,” or “make it better.”
A scorecard turns judgement into a repeatable comparison.
It helps answer practical questions:
- Did the new prompt improve the result?
- Is a different model worth the extra cost?
- Which errors keep returning?
- Is the workflow ready for a pilot?
Start with the task outcome
Write one sentence describing success.
Example:
Produce a customer-reply draft that answers the enquiry from approved service information, avoids unauthorised promises, matches the business tone, and takes less than two minutes to review.
The scorecard should measure that outcome, not generic writing quality.
A practical six-part scorecard
Score each dimension from 0 to 2.
1. Correctness
- 0: Material facts or decisions are wrong.
- 1: Mostly correct but needs a meaningful correction.
- 2: Correct against the approved evidence.
2. Completeness
- 0: Misses the main requirement.
- 1: Covers the task but omits a useful or required part.
- 2: Includes all required content without unnecessary padding.
3. Evidence
- 0: Claims are unsupported or sources are invented.
- 1: Evidence is partly traceable or citations need repair.
- 2: Important claims map clearly to approved sources.
4. Boundaries and escalation
- 0: Guesses, exceeds authority, or misses a required escalation.
- 1: Stays mostly within scope but needs a warning or handoff adjustment.
- 2: Follows boundaries and escalates correctly.
5. Usability
- 0: Wrong format or unusable by the next person or system.
- 1: Usable after restructuring.
- 2: Ready for the next workflow step.
6. Review effort
- 0: Slower to fix than completing the task manually.
- 1: Produces a modest net saving.
- 2: Produces a clear saving after review.
Maximum score: 12.
Define critical failures
Some errors should fail the output regardless of its total.
Examples:
- Discloses personal or confidential information.
- Invents a price, deadline, refund, guarantee, or legal requirement.
- Gives unsafe instructions.
- Sends or changes something without required approval.
- Fabricates a source or quotation.
- Fails to escalate a high-impact decision.
Mark these separately. Do not let excellent tone compensate for a serious control failure.
Build a representative evaluation set
Use the same examples when comparing versions.
Include ordinary, difficult, incomplete, conflicting, and out-of-scope cases. If the work changes over time, refresh the set without removing historic failure cases.
The NIST AI Risk Management Framework and NIST’s broader generative AI evaluation program emphasise testing and measurement of model capabilities and limitations. For a business, the test set is where that principle becomes operational.
Calibrate human reviewers
Ask two people to score the same small sample, then compare their reasoning.
If one reviewer gives a 2 for correctness and another gives 0, the rubric or evidence is unclear.
Resolve:
- What source is authoritative.
- Which omissions matter.
- What tone is acceptable.
- Which actions require escalation.
- What counts as a material correction.
A scorecard cannot be more precise than the business process behind it.
Use AI-assisted grading carefully
AI can apply a well-defined rubric to many outputs and flag likely failures. It is useful for triage and consistent formatting.
However:
- Calibrate it against human-reviewed examples.
- Do not let it grade facts without access to the source.
- Test whether wording, length, or style biases the score.
- Keep human review for high-impact evaluation decisions.
Record the result by failure type
Do not keep only the total score.
Track:
- Average score by dimension.
- Critical-failure rate.
- Correct escalation rate.
- Average human review time.
- Most common correction.
- Performance by case type.
Averages can hide a workflow that performs well on simple cases and fails badly on important exceptions.
Set a rollout threshold
For example:
- No critical failures in the final holdout set.
- At least 90% correct escalation on defined risk cases.
- Average score of 10 or higher.
- Median review time below the manual baseline.
Those numbers are examples, not universal standards. Choose thresholds that match the risk and value of the task.
Use the scorecard inside your AI workflow test and improve it when the AI review checklist uncovers a new failure. Rising Tide’s workflow setup can turn these measures into a practical pilot rather than a one-off demo.